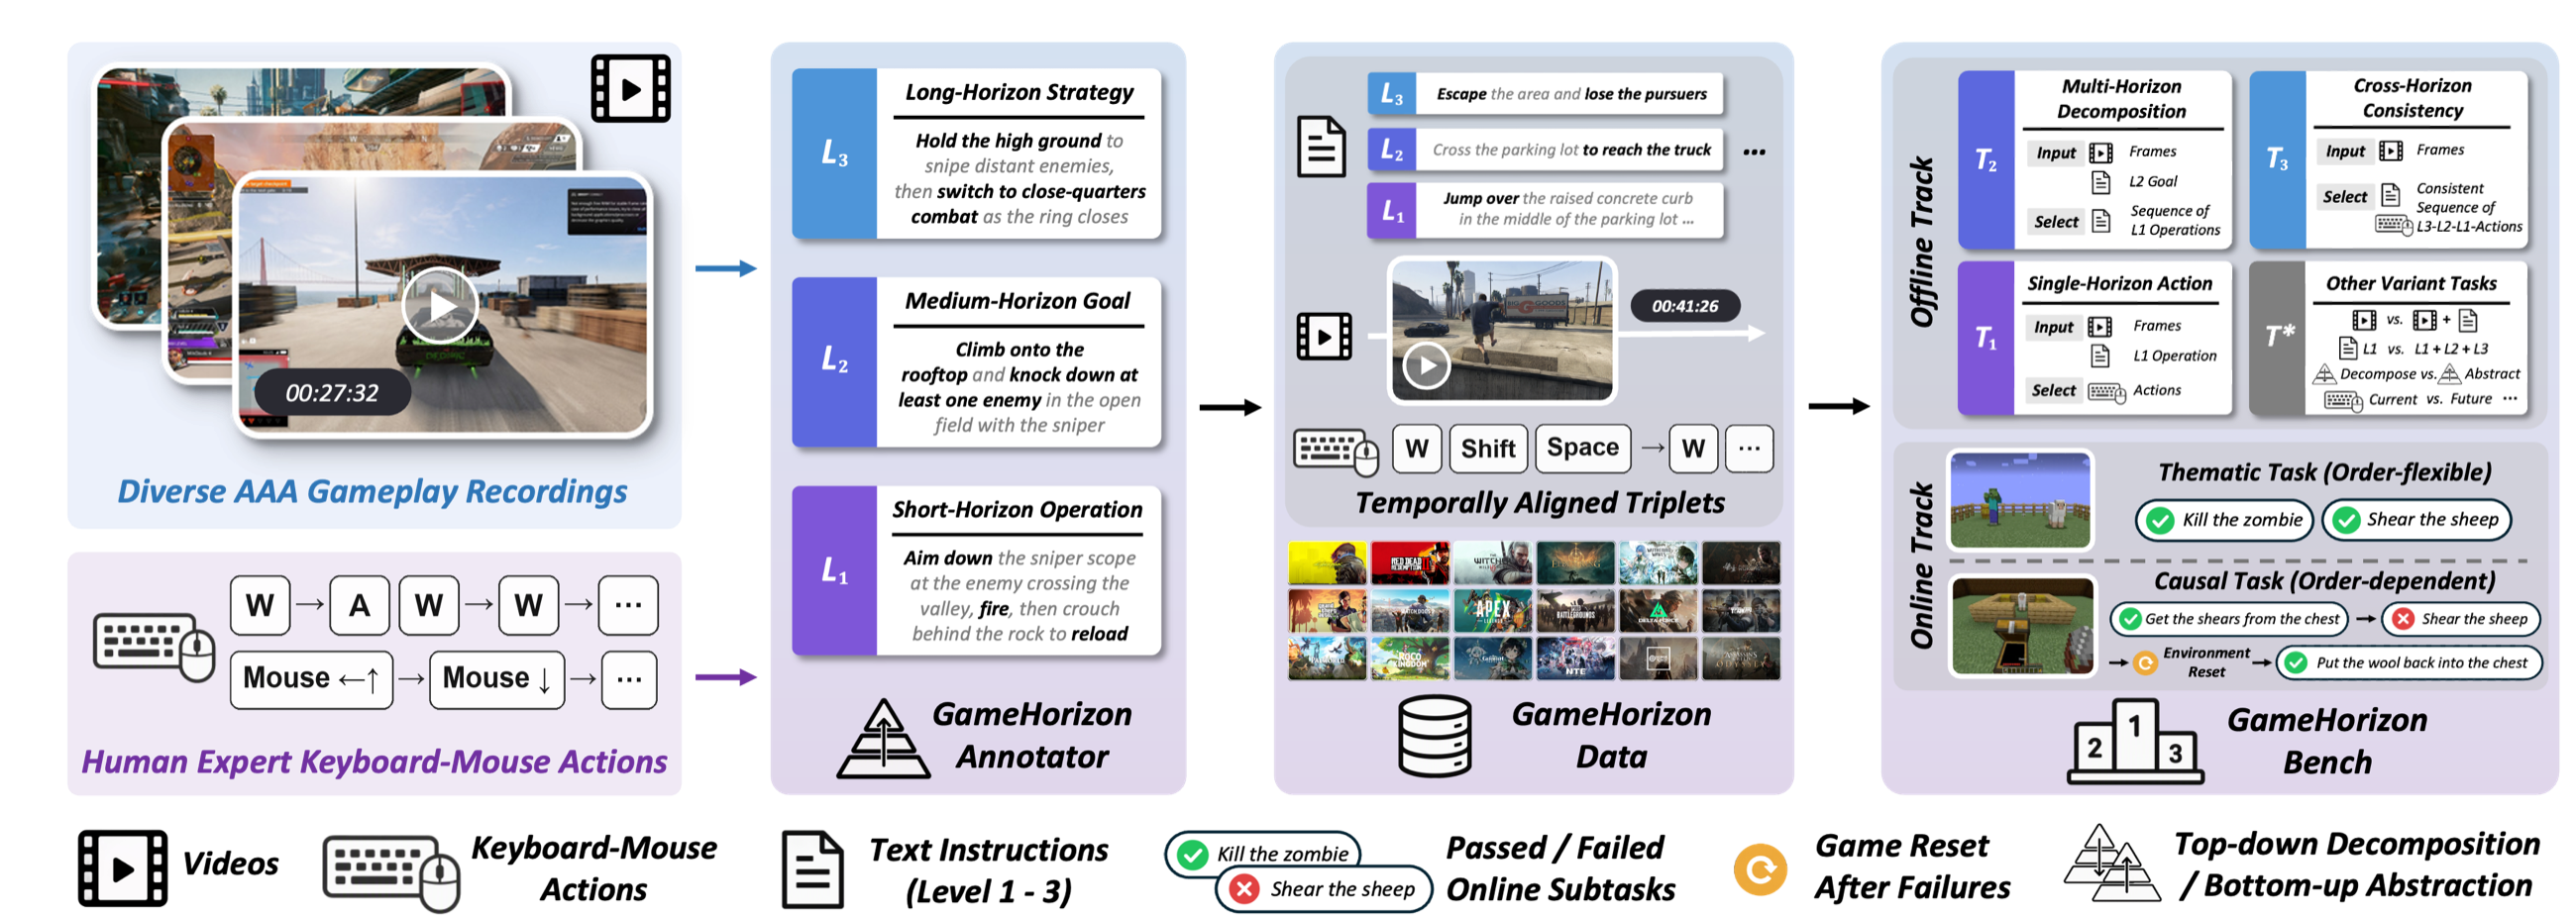
GameHorizon-Annotator is a scalable and automated pipeline. It combines action-aware segmentation, bottom-up temporal merging, and VLM annotation to annotate gameplay trajectories with the three-level instructions.
GameHorizon-Data is the first large-scale AAA game corpus with temporally aligned video recordings, player actions, and multi-horizon instructions across diverse AAA game genres. It comprises 5,000-hour videos in 21 games.
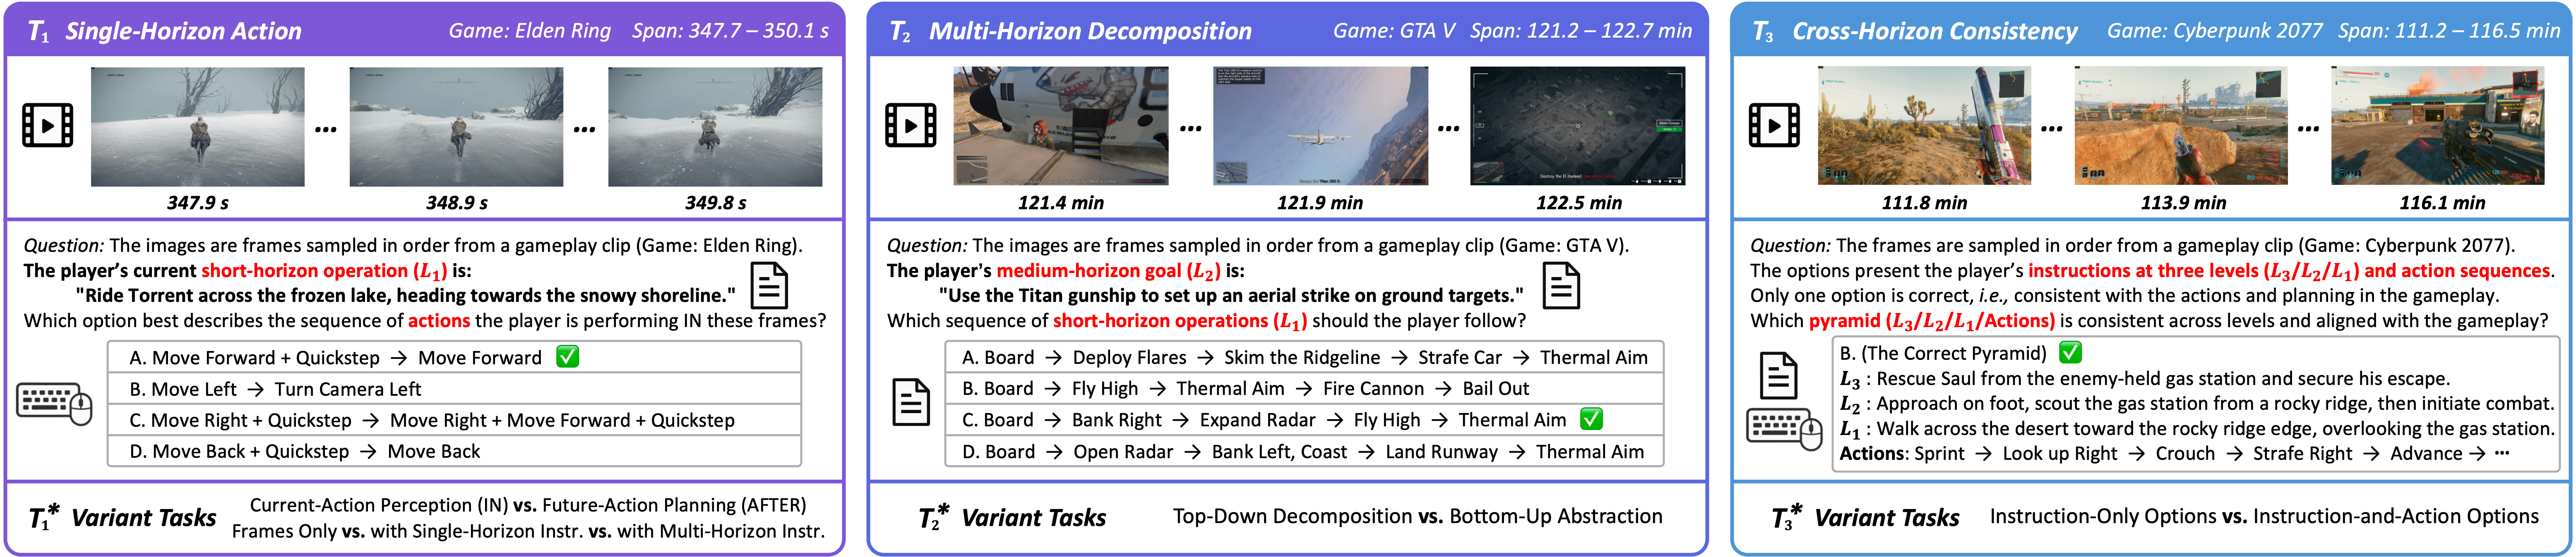
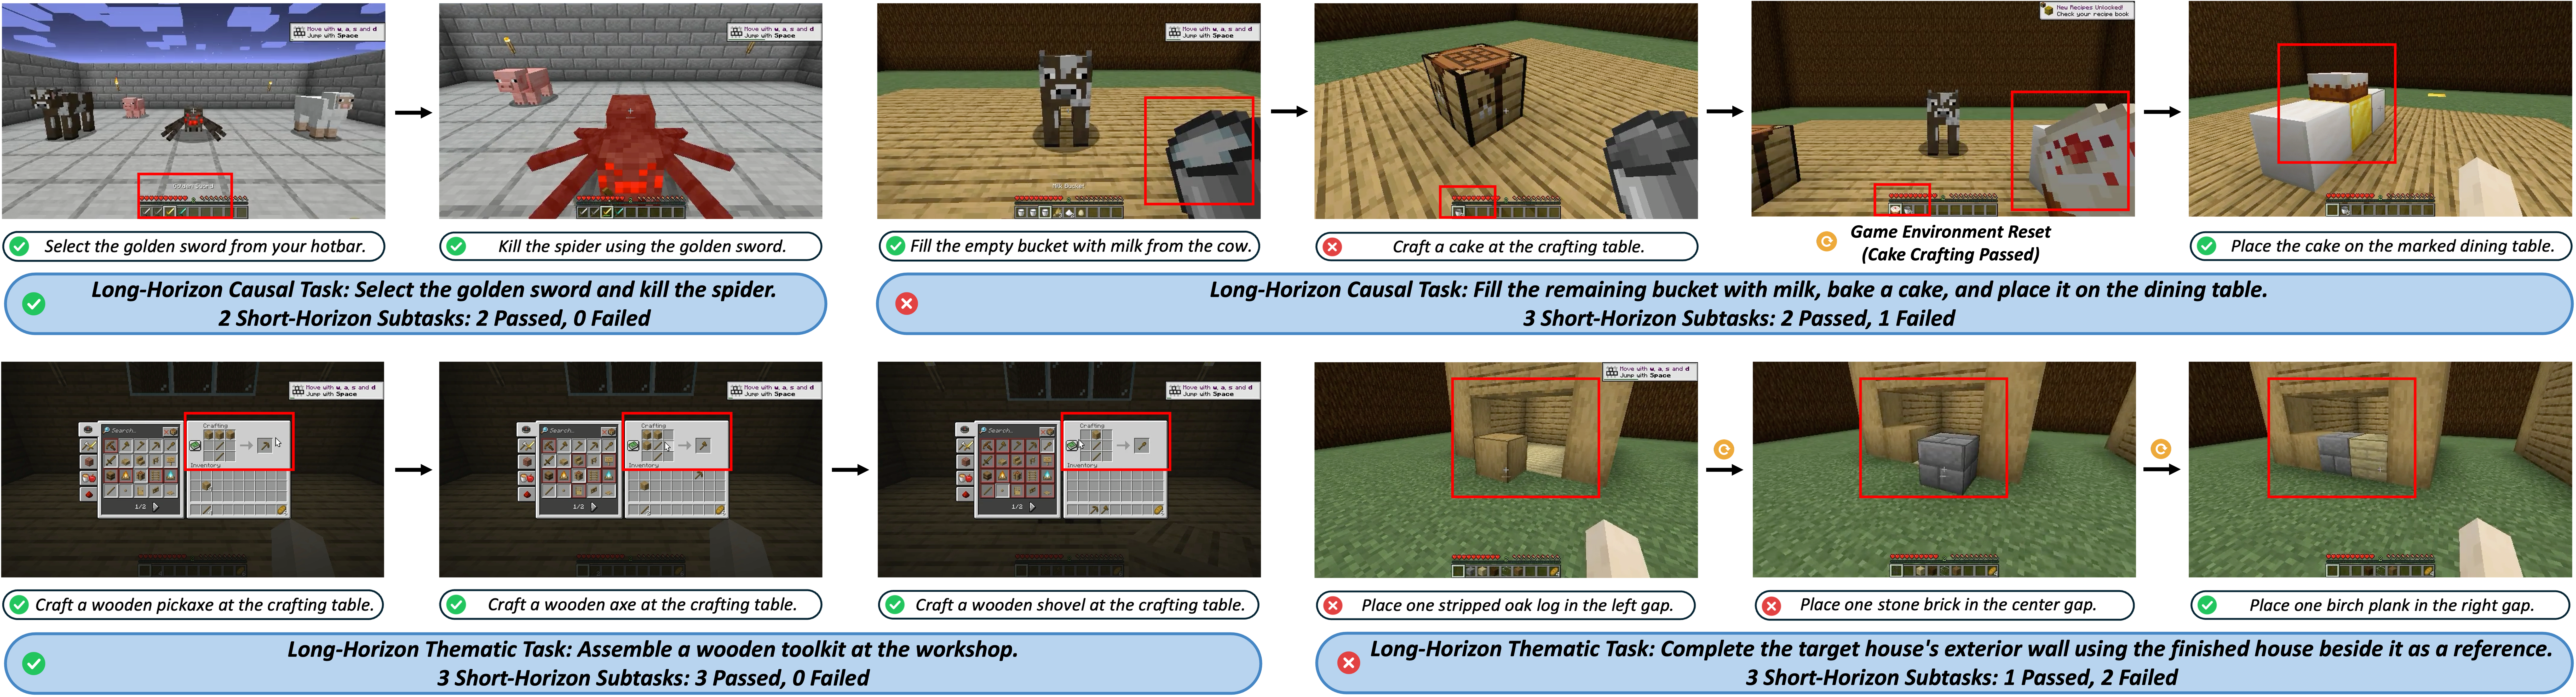
GameHorizon-Bench consists of reproducible offline evaluation, stepwise online testing, as well as fine-grained failure diagnosis across diverse model families. We test 47 models in VLMs, UMMs, GUI, coding, and game agents.
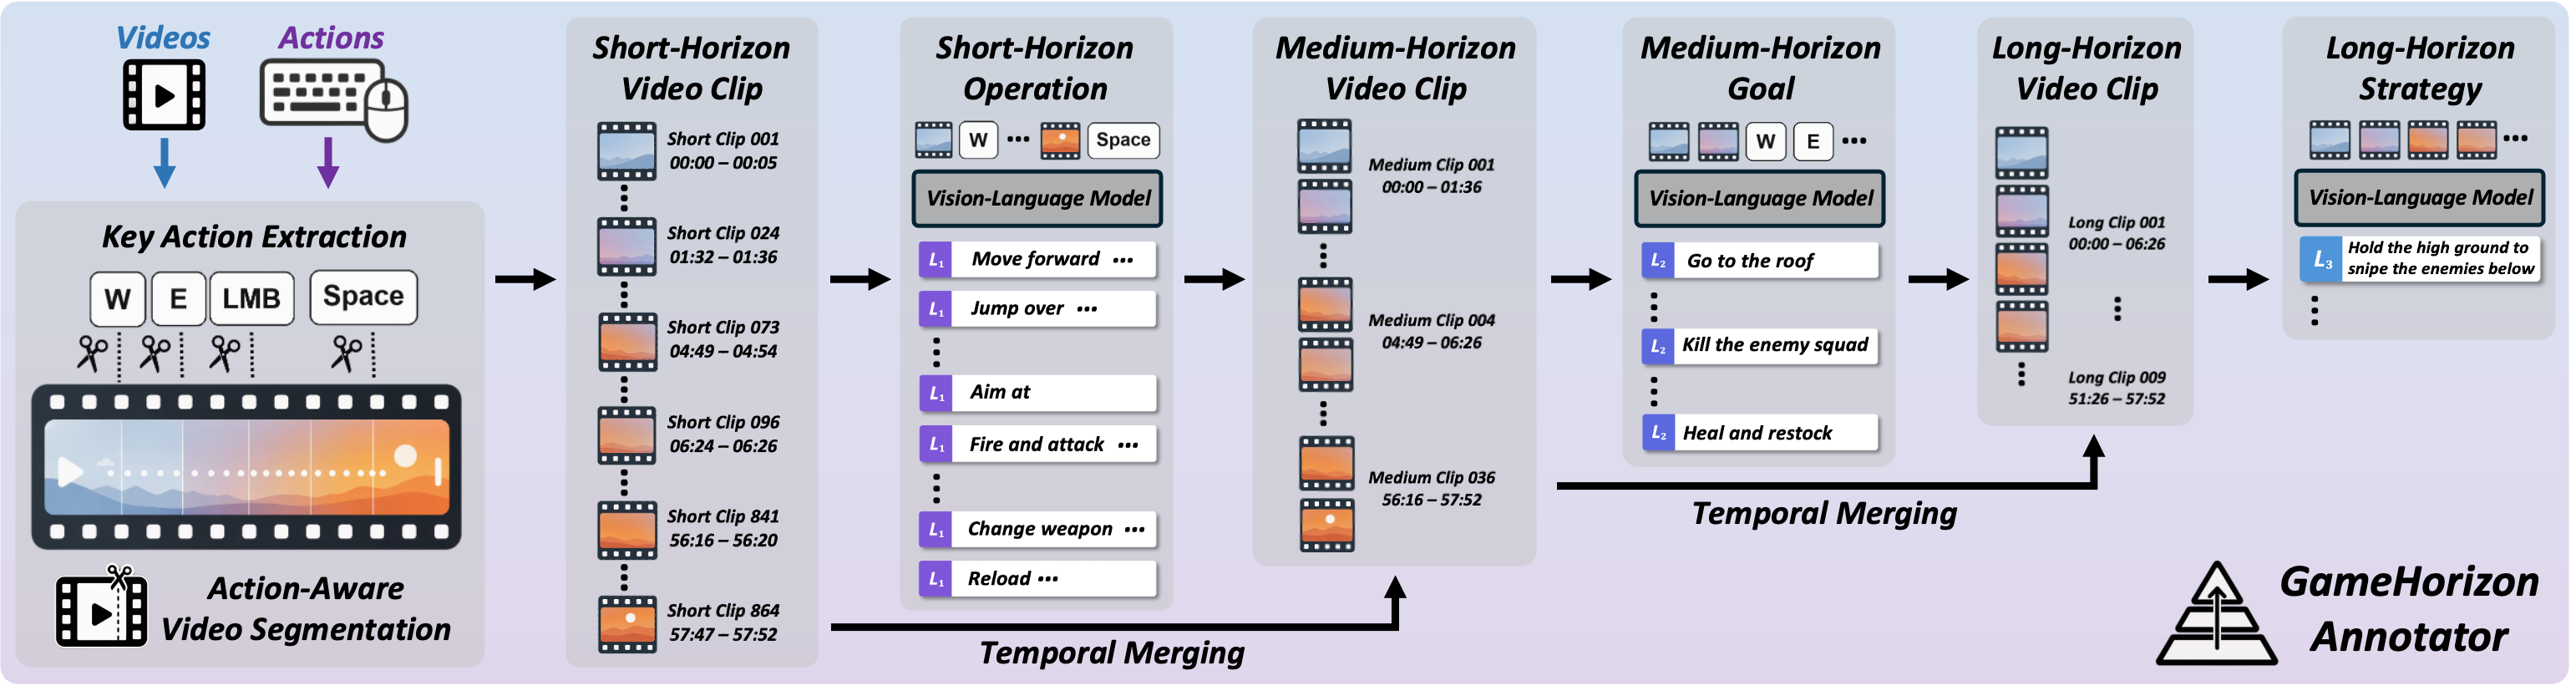
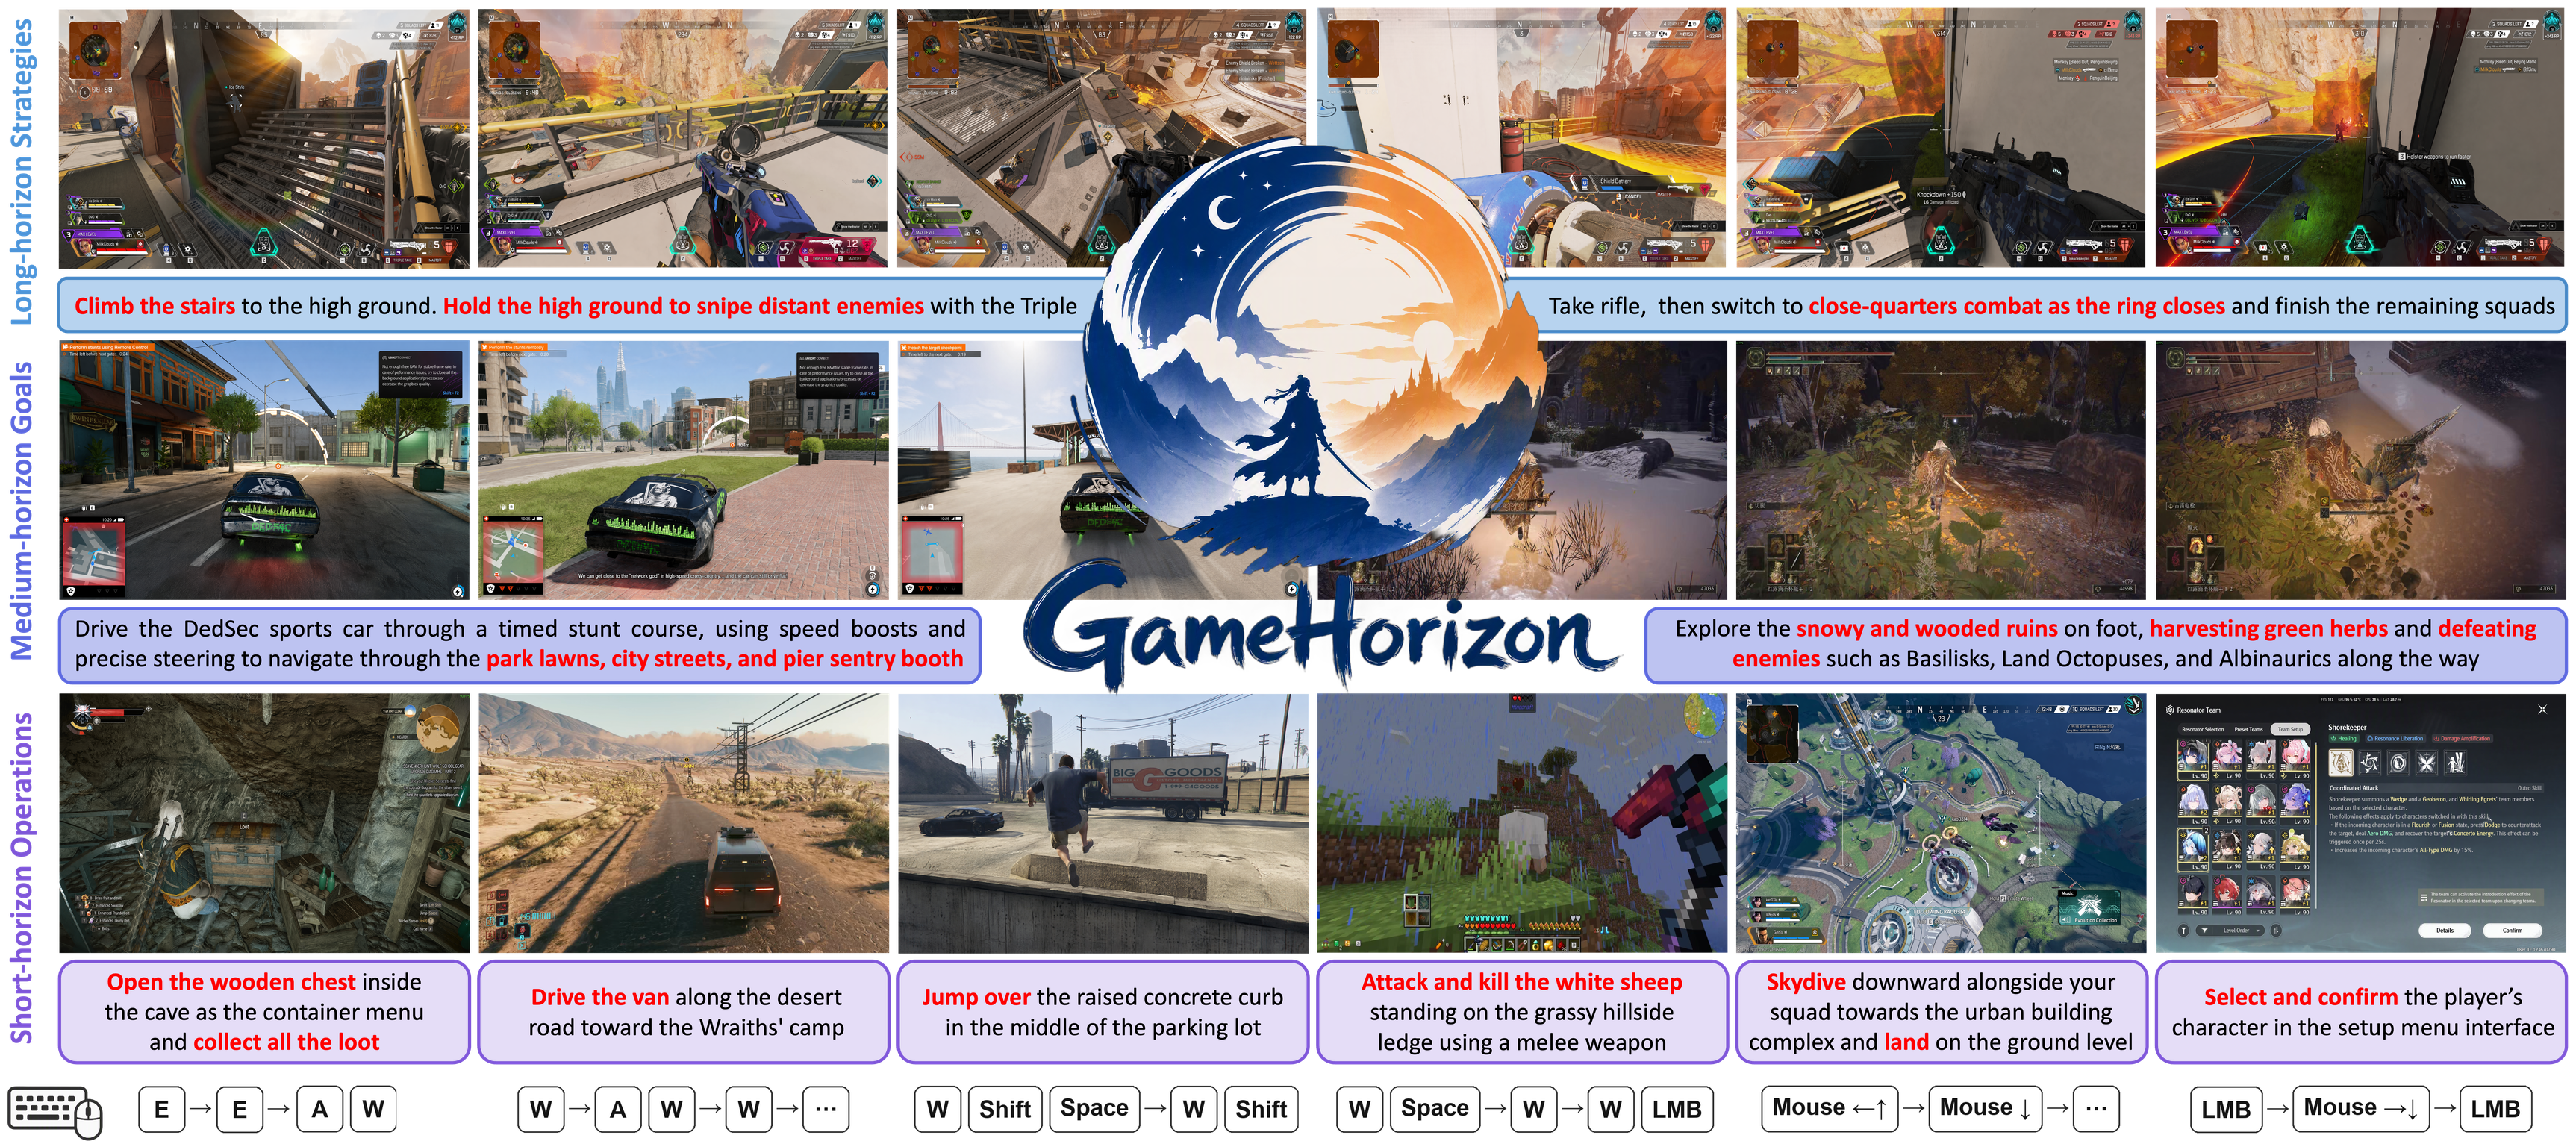
21 AAA titles, 5,000 hours of gameplay. GameHorizon-Data is the first large-scale AAA gameplay dataset with temporally aligned videos, player actions, and multi-horizon instructions. The game trajectories are collected by 100 experienced human players. It spans five diverse game genres, such as the open-world, action role-playing, competitive shooter, sandbox survival, and creature-collecting adventure. It provides a reliable data foundation for evaluating gameplay abilities across models.
| Game Title | Recording Duration and Share | Annotation Counts | Avg. Instruction Span (s) | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Total (h) | Share (%) | Valid Rate (%) | Valid (h) | Actions (104) | L1 | L2 | L3 | L1 | L2 | L3 | |
| Valorant | 617.5 | 12.35 | 86.4 | 533.8 | 5,811 | 705,380 | 23,113 | 5,778 | 2.72 | 83.1 | 332.5 |
| Minecraft | 589.8 | 11.80 | 84.5 | 498.3 | 5,087 | 448,166 | 21,715 | 5,429 | 4.00 | 82.6 | 330.4 |
| Grand Theft Auto V | 566.1 | 11.32 | 86.5 | 489.9 | 3,585 | 382,302 | 21,644 | 5,411 | 4.61 | 81.5 | 325.9 |
| Palworld | 438.7 | 8.77 | 83.5 | 366.5 | 3,741 | 329,615 | 15,971 | 3,993 | 4.00 | 82.6 | 330.4 |
| Delta Force | 337.0 | 6.74 | 85.1 | 286.9 | 3,123 | 379,091 | 12,422 | 3,105 | 2.72 | 83.1 | 332.5 |
| Roco Kingdom: World | 329.2 | 6.58 | 91.9 | 302.4 | 2,677 | 786,446 | 13,054 | 3,263 | 1.38 | 83.4 | 333.6 |
| Red Dead Redemption 2 | 304.4 | 6.09 | 85.9 | 261.6 | 1,992 | 202,428 | 11,553 | 2,888 | 4.65 | 81.5 | 326.1 |
| Cyberpunk 2077 | 301.2 | 6.02 | 87.9 | 264.7 | 2,574 | 192,222 | 11,646 | 2,912 | 4.96 | 81.8 | 327.3 |
| Genshin Impact | 232.6 | 4.65 | 90.4 | 210.4 | 1,862 | 547,134 | 9,082 | 2,270 | 1.38 | 83.4 | 333.6 |
| PUBG: Battlegrounds | 197.4 | 3.95 | 84.6 | 167.0 | 1,818 | 220,726 | 7,233 | 1,808 | 2.72 | 83.1 | 332.5 |
| Elden Ring Nightreign | 168.9 | 3.38 | 90.0 | 152.0 | 1,348 | 250,877 | 6,630 | 1,658 | 2.18 | 82.6 | 330.2 |
| The Witcher 3: Wild Hunt | 158.7 | 3.17 | 89.4 | 141.8 | 1,323 | 287,433 | 6,290 | 1,573 | 1.78 | 81.2 | 324.6 |
| Elden Ring | 135.9 | 2.72 | 92.6 | 125.9 | 1,116 | 207,706 | 5,489 | 1,372 | 2.18 | 82.6 | 330.2 |
| Escape from Tarkov | 119.8 | 2.40 | 81.7 | 97.9 | 1,065 | 129,320 | 4,237 | 1,059 | 2.72 | 83.1 | 332.5 |
| Apex Legends | 116.5 | 2.33 | 85.3 | 99.4 | 1,082 | 131,381 | 4,305 | 1,076 | 2.72 | 83.1 | 332.5 |
| Wuthering Waves | 108.4 | 2.17 | 89.1 | 96.5 | 819 | 294,088 | 4,077 | 1,019 | 1.18 | 85.2 | 341.0 |
| Neverness to Everness | 101.3 | 2.03 | 89.3 | 90.4 | 800 | 235,145 | 3,903 | 976 | 1.38 | 83.4 | 333.6 |
| Assassin's Creed | 51.1 | 1.02 | 87.0 | 44.5 | 338 | 34,401 | 1,963 | 491 | 4.65 | 81.5 | 326.1 |
| Black Myth: Wukong | 51.1 | 1.02 | 91.3 | 46.6 | 414 | 76,971 | 2,034 | 509 | 2.18 | 82.6 | 330.2 |
| Watch Dogs 2 | 38.5 | 0.77 | 85.0 | 32.7 | 249 | 25,324 | 1,445 | 361 | 4.65 | 81.5 | 326.1 |
| Honor of Kings: World | 35.9 | 0.72 | 87.3 | 31.3 | 277 | 81,429 | 1,352 | 338 | 1.38 | 83.4 | 333.6 |
| Total / Avg. | 5,000 | 100.00 | 86.8 | 4,341 | 41,103 | 5,947,588 | 189,158 | 47,290 | 2.63 | 82.6 | 330.4 |
| Dataset | Data Scope | Annotation Properties | Notes | ||||
|---|---|---|---|---|---|---|---|
| Large-Scale | AAA-Focused | Direct Human Actions | Instruction Annotations | Dense Instructions | Multi-Horizon | ||
| Single-Game Datasets | |||||||
| MineRL (Guss et al., 2019) | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | Minecraft; human actions; no textual instructions. |
| MineDojo (Fan et al., 2022) | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ | Web Minecraft videos; no actions or instructions. |
| VPT (Baker et al., 2022) | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ | Web Minecraft videos; IDM actions; no instructions. |
| STEVE-1 (Lifshitz et al., 2023) | ✗ | ✗ | ✓ | ✓ | ✗ | ✗ | Minecraft; only 10K short-term text instructions. |
| PLAICraft (He et al., 2025) | ✓ | ✗ | ✓ | ✗ | ✗ | ✗ | Minecraft; human actions; no textual instructions. |
| WildWorld (Li et al., 2026) | ✗ | ✓ | ✗ | ✗ | ✗ | ✗ | Monster Hunter Wilds; AI actions; no instructions. |
| EgoCS-400K (Guo et al., 2026) | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | CS; replay-derived action labels; no instructions. |
| Multi-Game Datasets | |||||||
| NitroGen (Magne et al., 2026) | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ | Gamepad-overlay actions without text instructions. |
| Open-P2P (Yue et al., 2026) | ✓ | ✗ | ✓ | ✓ | ✗ | ✗ | Majority non-AAA games; sparse text instructions. |
| D2E (Choi et al., 2026) | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | Mostly IDM-inferred actions; no text instructions. |
| Gaming-500-hours (Markov AI, 2026) | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | Majority non-AAA games; no textual instructions. |
| GameHorizon-Data (Ours) | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | AAA; human actions; dense multi-horizon instructions. |
| # | Model | T1 | T2 | T3 | Overall |
|---|---|---|---|---|---|
| 1 | GPT-6-Astra | 69.4 | 79.6 | 91.5 | 80.2 |
| 2 | Gemini 3.8 Flash | 65.9 | 81.2 | 84.8 | 77.3 |
| 3 | Gemini 3.7 Flash | 66.2 | 80.1 | 83.9 | 76.7 |
| 4 | Gemini 3.6 Flash | 62.3 | 79.1 | 84.6 | 75.3 |
| 5 | GPT-5.6 Sol | 65.3 | 77.5 | 81.5 | 74.8 |
| 6 | Kimi-K3 | 64.4 | 79.3 | 79.7 | 74.5 |
| 7 | Gemini 3.5 Flash | 64.9 | 77.4 | 80.8 | 74.4 |
| 8 | GPT-5.5 | 64.6 | 78.9 | 76.2 | 73.2 |
| 9 | Gemini 3.1 Pro | 64.5 | 75.8 | 78.2 | 72.8 |
| 10 | Doubao-Seed-2.1-Turbo | 63.1 | 79.4 | 75.5 | 72.7 |
| 11 | Doubao-Seed-2.1-Pro | 62.9 | 76.7 | 76.6 | 72.1 |
| # | Model | T1 | T2 | T3 | Overall |
|---|---|---|---|---|---|
| 12 | Doubao-Seed-2.0-Pro | 59.2 | 74.9 | 80.0 | 71.4 |
| 13 | Claude Fable 5 | 62.9 | 72.7 | 78.1 | 71.2 |
| 14 | GPT-5.6 Terra | 62.1 | 75.6 | 74.4 | 70.7 |
| 15 | Qwen3.7-Plus | 58.8 | 75.9 | 71.5 | 68.7 |
| 16 | Qwen3.8-27B | 59.9 | 77.4 | 68.1 | 68.5 |
| 17 | GPT-5.6 Luna | 61.6 | 70.7 | 71.1 | 67.8 |
| 17 | Kimi-K2.6 | 61.2 | 73.2 | 69.0 | 67.8 |
| 19 | Doubao-Seed-2.0-Lite | 55.2 | 69.0 | 76.3 | 66.8 |
| 20 | Gemma 4 31B-IT | 53.8 | 68.6 | 76.6 | 66.3 |
| 21 | MiniMax-M3 | 57.8 | 68.5 | 70.6 | 65.6 |
| 22 | Qwen3-VL-235B-A22B-Thinking | 58.2 | 71.6 | 65.9 | 65.2 |
| # | Model | T1 | T2 | T3 | Overall |
|---|---|---|---|---|---|
| 23 | Claude Opus 4.8 | 59.1 | 62.1 | 73.1 | 64.8 |
| 24 | Claude Sonnet 5 | 54.4 | 57.7 | 82.0 | 64.7 |
| 25 | Step-3.7-Flash | 57.5 | 71.3 | 63.4 | 64.1 |
| 26 | Qwen3-VL-235B-A22B-Instruct | 55.1 | 62.1 | 73.1 | 63.4 |
| 27 | GLM-5V-Turbo | 53.4 | 65.4 | 70.8 | 63.2 |
| 28 | GPT-5.2 | 58.9 | 58.9 | 70.6 | 62.8 |
| 29 | Qwen3.5-397B-A17B | 53.3 | 60.1 | 73.5 | 62.3 |
| 30 | BAGEL-7B-MoT | 51.7 | 57.3 | 75.1 | 61.4 |
| 31 | Qwen2.5-VL-32B-Instruct | 54.8 | 58.0 | 69.7 | 60.8 |
| 32 | Step3-VL-10B | 55.4 | 64.7 | 61.7 | 60.6 |
| 33 | SenseNova-U1-8B-MoT | 48.2 | 59.2 | 67.5 | 58.3 |
| # | Model | T1 | T2 | T3 | Overall |
|---|---|---|---|---|---|
| 34 | Qwen3.6-35B-A3B | 53.3 | 52.9 | 66.3 | 57.5 |
| 35 | Qwen3-Omni-30B-A3B-Instruct | 52.5 | 55.6 | 63.7 | 57.3 |
| 36 | GELab-Zero-4B-Preview | 51.8 | 46.8 | 72.7 | 57.1 |
| 37 | Qwen2.5-VL-7B-Instruct | 52.0 | 54.3 | 63.7 | 56.7 |
| 38 | InternVL3.5-8B | 51.8 | 50.2 | 65.5 | 55.8 |
| 39 | GLM-4.1V-9B-Thinking | 54.9 | 54.8 | 55.3 | 55.0 |
| 40 | GPT-4o | 55.7 | 46.3 | 61.3 | 54.4 |
| 41 | UI-TARS-1.5-7B | 49.1 | 47.1 | 62.9 | 53.0 |
| 42 | Ovis-U1-3B | 44.7 | 39.6 | 59.2 | 47.8 |
| 43 | InternVL3.5-2B | 45.1 | 40.3 | 54.7 | 46.0 |
| 44 | InternVL-U-4B | 46.1 | 37.9 | 49.8 | 44.6 |
| Online Rank | Model | Offline Rank | Short-Horizon Subtasks | Long-Horizon Tasks | Causal | Thematic |
|---|---|---|---|---|---|---|
| 1 | GPT-6-Astra | 1 | 66.1(41/62) | 45.0(9/20) | 40.0(4/10) | 50.0(5/10) |
| 2 | Gemini 3.6 Flash | 4 | 56.5(35/62) | 30.0(6/20) | 30.0(3/10) | 30.0(3/10) |
| 3 | Kimi-K3 | 6 | 46.8(29/62) | 10.0(2/20) | 20.0(2/10) | 0.0(0/10) |
| Online Rank | Model | Offline Rank | Short-Horizon Subtasks | Long-Horizon Tasks | Causal | Thematic |
|---|---|---|---|---|---|---|
| 4 | GPT-5.6 Terra | 14 | 37.1(23/62) | 10.0(2/20) | 20.0(2/10) | 0.0(0/10) |
| 5 | GPT-5.6 Luna | 17 | 33.9(21/62) | 10.0(2/20) | 10.0(1/10) | 10.0(1/10) |
| 6 | MiniMax-M3 | 21 | 29.0(18/62) | 10.0(2/20) | 10.0(1/10) | 10.0(1/10) |
| Online Rank | Model | Offline Rank | Short-Horizon Subtasks | Long-Horizon Tasks | Causal | Thematic |
|---|---|---|---|---|---|---|
| 7 | GLM-5V-Turbo | 27 | 27.4(17/62) | 5.0(1/20) | 10.0(1/10) | 0.0(0/10) |
| 8 | Qwen3.5-397B-A17B | 29 | 19.4(12/62) | 5.0(1/20) | 10.0(1/10) | 0.0(0/10) |
| 9 | Step3-VL-10B | 32 | 14.5(9/62) | 5.0(1/20) | 10.0(1/10) | 0.0(0/10) |
| Online Rank | Model | Offline Rank | Short-Horizon Subtasks | Long-Horizon Tasks | Causal | Thematic |
|---|---|---|---|---|---|---|
| 10 | Qwen3.6-35B-A3B | 34 | 11.3(7/62) | 5.0(1/20) | 10.0(1/10) | 0.0(0/10) |
| 11 | InternVL3.5-8B | 38 | 3.2(2/62) | 0.0(0/20) | 0.0(0/10) | 0.0(0/10) |
| 12 | UI-TARS-1.5-7B | 41 | 1.6(1/62) | 0.0(0/20) | 0.0(0/10) | 0.0(0/10) |
| Benchmark | Benchmark Scope | Annotation Properties | Evaluation Settings | Notes | |||
|---|---|---|---|---|---|---|---|
| Model Diversity | AAA-Focused | Direct Human Actions | Multi-Horizon | Reproducible Offline | Stepwise Online | ||
| Single-Game Benchmarks | |||||||
| MineDojo (Fan et al., 2022) | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | Online success rates in Minecraft; the game agents only. |
| MCU (Zheng et al., 2025) | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | Minecraft; VLM-based online scores; game agents only. |
| MineExplorer (Ju et al., 2026) | ✗ | ✗ | ✗ | ✗ | ✗ | ✓ | Online milestone rates in Minecraft; the VLMs only. |
| Multi-Game Benchmarks | |||||||
| BALROG (Paglieri et al., 2025) | ✗ | ✗ | ✗ | ✗ | ✗ | ✓ | Non-AAA; the online progress scores; LLMs and VLMs. |
| VideoGameBench (Zhang et al., 2025) | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | Retro and classic games; online scores and VLMs only. |
| Orak (Park et al., 2026) | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ | Majority non-AAA; the online scores; LLMs and VLMs. |
| GameWorld (Ouyang et al., 2026) | ✗ | ✗ | ✗ | ✗ | ✗ | ✓ | Browser mini-games; online scores; VLM agents. |
| GameVerse (Zhang et al., 2026) | ✗ | ✗ | ✗ | ✗ | ✗ | ✓ | Mostly non-AAA; online milestone scores; VLM agents. |
| GameHorizon-Bench (Ours) | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | AAA; reproducible offline; stepwise online; diverse models. |
@article{GameHorizonSuite2026,
  title   = {GameHorizon Suite: Multi-Horizon Data and Evaluation in Gameplay},
  author  = {Yiran Wang and Xingyilang Yin and Junfu Pu and Guangzhi Wang and Kaifeng Li and Mingyu Ouyang and Huiqiang Sun and Lingen Li and Cheng Cheng and Wangbo Yu and Honghao Chen and Xiaodong Cun and Chi-Man Pun and Zhiguo Cao and Ying Shan},
  year    = {2026},
  journal = {arXiv preprint arXiv:2609.25001},
  url     = {https://arxiv.org/abs/2609.25001}
}